n-seo reads Search Console and GA4 every morning, probes your sites for what quietly broke, and ranks the moves worth making. Your model — Claude, GPT, something local, your choice — turns those findings into proposals and briefings. Your coding agent works the queue over MCP. It proposes; it never posts, publishes or edits a site.
npm install -g n-seo then n-seo init my-sites
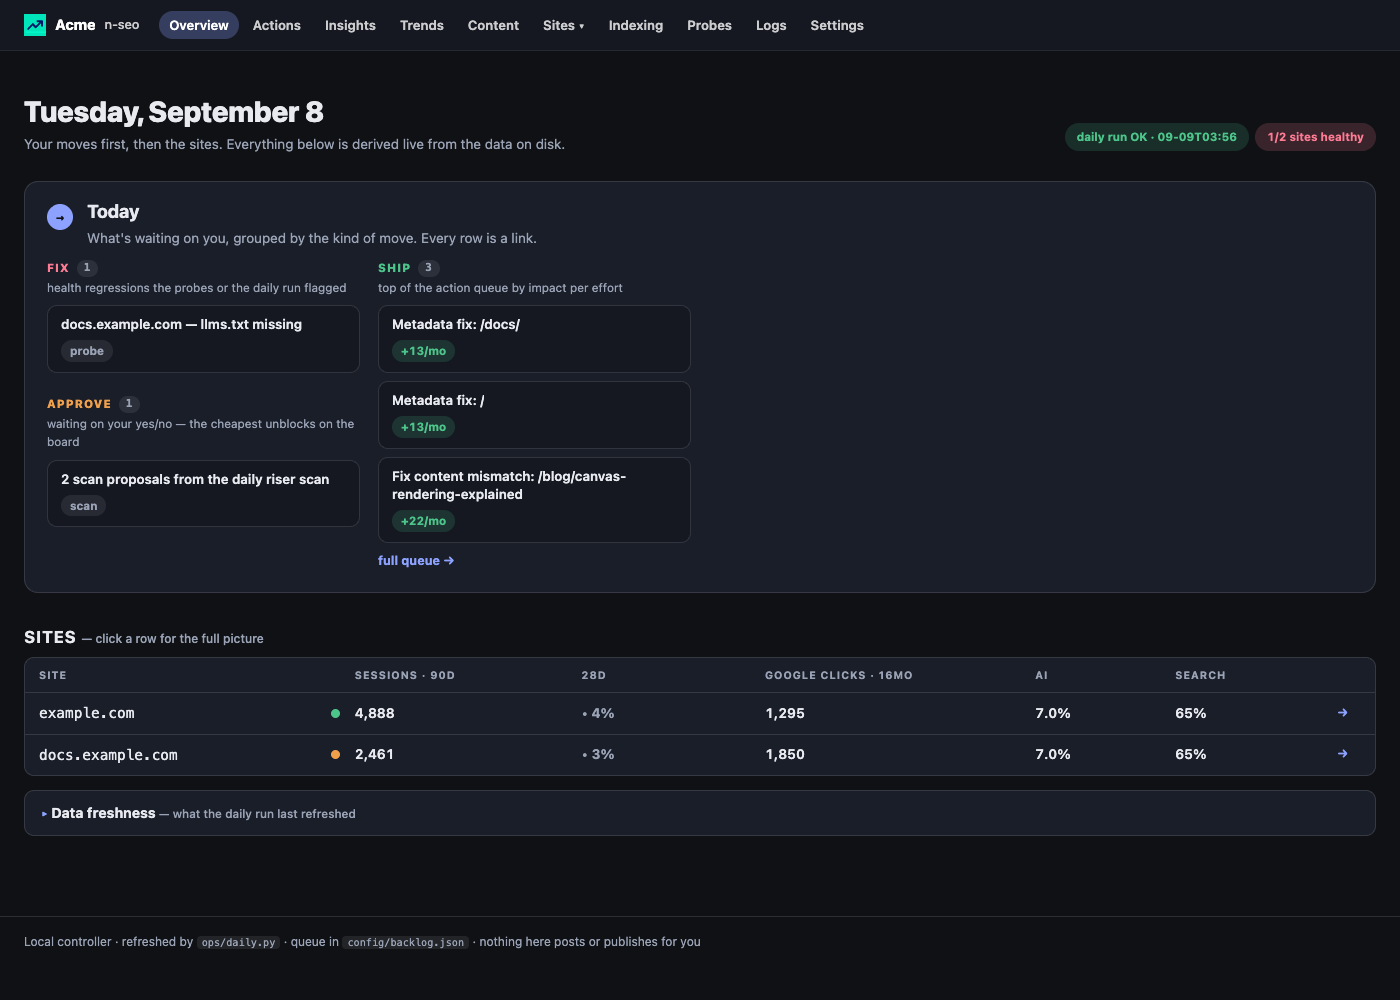
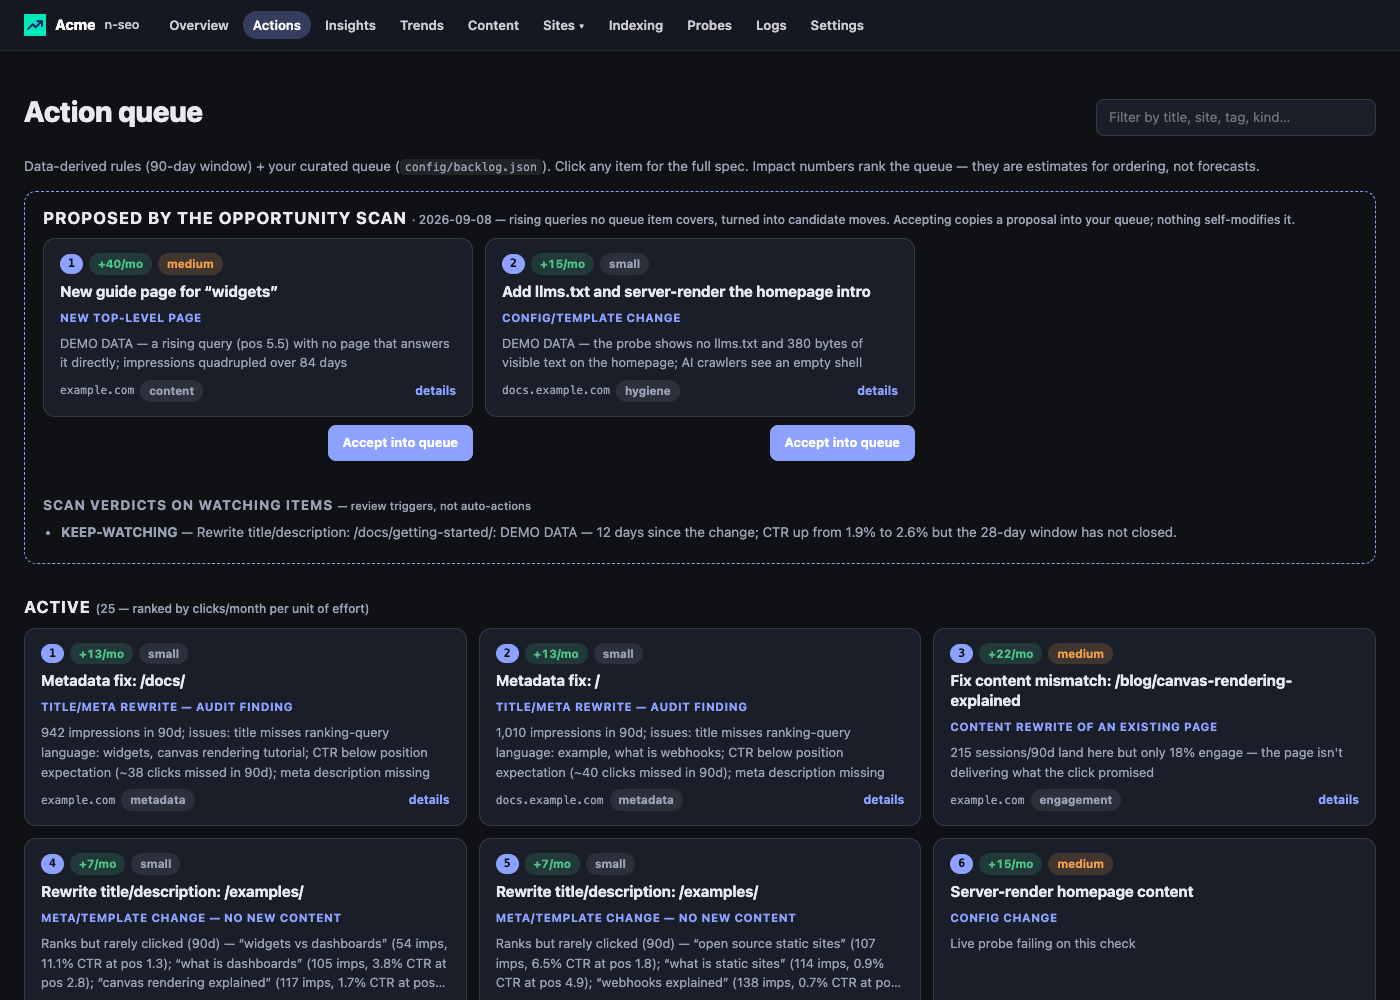
This is the actual dashboard, built from this commit, on the synthetic dataset n-seo demo gives you. Click anything.
Laptop, VPS, NAS or a VM in your own cloud. No account, no SaaS, no telemetry. The only things that leave the host are the Google APIs you authorize, the model provider you configure, and one daily npm view to see whether a new version shipped — that last one switchable off in a line.
Proposals, verdicts and briefings come from the provider you configure — Anthropic, any OpenAI-compatible endpoint, or a CLI on your machine. No key ships with n-seo and nothing is called that you did not set up.
Every card shows the queries, positions and impressions behind it, then the move, then a spec. You learn what actually moves the numbers.
No module edits a site, sends an email or posts a comment. Machine proposals wait in a holding area until you accept them. The words are always yours.
n-seo is deterministic where it should be — the pulls, the probes and the ranking rules are plain code you can read. Everything that needs judgment is handed to a model you choose, and everything that changes a site is handed to you.
Point modules.llm at a provider and the morning run stops being a report and starts being a colleague:
Reach it however you like: any CLI that reads a prompt on stdin — claude -p or ollama run or a shell script — or an HTTP endpoint, Anthropic or anything OpenAI-compatible, gateways and local servers included. Turn it off and you still get the full data-derived queue; you lose the proposals, verdicts and briefings.
A read-only MCP server exposes the queue, per-site metrics, the metadata audit, index coverage, trends and ops health. Claude Code picks it up from .mcp.json with no setup; other clients use stdio or an authenticated HTTP endpoint.
n-seo init installs seven skills into your instance — orient, setup, add-site, triage, ship, review, deploy — with a CLAUDE.md carrying the operating rules. Open the directory in Claude Code and it is already oriented: no docs to read first, and the rules are enforced rather than merely documented. ship stops rather than crossing a 28-day freeze or the weekly metadata budget.
16 tools, 3 doc resources, every one annotated read-only. MCP docs →
It reads your sites the way Google sees them — through the Search Console and GA4 APIs — so it never needs a copy of their code. n-seo init makes one directory of its own and everything it writes stays there.
Opening your website and running init there.
~/code/my-website/ your app ├── .git/ ├── package.json ├── src/ └── my-sites/ ← init ran here ├── n-seo.config.json committed to your site ├── config/backlog.json committed ├── .env committed └── data/ rewritten every morning, committed, then deployed
This is the mistake people make, so n-seo init now refuses it. It stops when the target holds a package.json or sits in a git repo it does not own, and prints the command you wanted instead.
One instance, watching every site you own.
~/ ├── code/ │ ├── my-website/ untouched │ └── docs-site/ untouched └── my-sites/ ← n-seo init my-sites ├── n-seo.config.json lists both sites ├── config/backlog.json your action queue ├── content/ drafts, campaigns ├── .claude/skills/ ask, don't read docs └── data/ gitignored, regenerable
Put it anywhere outside your repos — your home directory is fine. Give it a git repo of its own if you want the queue and the drafts to have history; the .gitignore that init writes already keeps the data out.
n-seo has no path to them and no reason to. When you ship a fix it is you, in your repo, on a branch, the way you already work.
A service account you create, added as a viewer on Search Console and GA4. It can read what Google already reports about your sites. That is all it can do.
Config, the queue, drafts, the daily log, the JSON the morning run pulls down. Delete the directory and nothing else on your machine changes.
The demo dataset populates every page, so you can see what the tool does before you connect anything. Node 20+, Python 3.10+ and curl are all it needs, on macOS, Linux or Windows.
# 1. the engine, once — a CLI, not a dependency npm install -g n-seo # 2. stand somewhere that is NOT a site repo cd ~ # 3. make the instance: ./my-sites — config, # queue, content, .mcp.json, seven skills n-seo init my-sites cd my-sites # 4. synthetic data, so every page has something n-seo demo # 5. the dashboard, reading this directory n-seo start # → http://localhost:4600 # then point it at your real sites — just ask claude # "set this up for my sites" # "what should I work on today?" # or by hand, after editing n-seo.config.json n-seo doctor # what access is missing n-seo daily # pull, probe, rank
Every page, every card, every chart — populated. Poke around the queue, open a spec, toggle a module in Settings.
One Google service account, added as a user on Search Console and GA4. The key is signed locally by node — no gcloud, no pip installs, no openssl. Say "set this up for my sites" and the n-seo-setup skill walks the whole thing, stopping at each decision that is yours. Step by step →
launchd on macOS, cron or systemd on Linux. It waits for the network, retries once, logs every step, and tells you when something failed. Scheduling →
In your own repo, your own way. The next morning's data says whether it worked, and the card moves to watching instead of disappearing.
Four planes. The first two are code; the third is you and your agent; the fourth is what keeps the second one honest.
Search Console (16 months and the trailing 90 days), GA4 sessions, sources and landing pages, per-page time series, URL Inspection verdicts for every sitemap URL, and a no-auth probe of each site: robots, sitemap, llms.txt, soft 404s, blocked AI crawlers, JS-only shells.
Rules over the 90-day window turn snapshots into actions: metadata that misses the ranking language, pages that rank well but rarely get clicked, queries sitting at position 5–15, landing pages that don't deliver what the click promised, traffic drops. Impact per unit of effort orders the queue. With the LLM module on, rising queries nothing covers become drafted proposals too.
Each card opens to the evidence, the move and a build spec. You change the title, add the section, fix the 404 — in your repo, on a branch, your way. Accept machine proposals into your queue with one click; nothing self-modifies it.
Shipped work becomes watching, never deleted. Watched pages are reported in the daily log; the scan judges whether a change succeeded, failed or needs more time. That feedback is how you hone your own principles.
Server-rendered, no bundler, light and dark. Compact, searchable, and split cleanly into active work and shipped work being measured.

Proposed → active → watching. Each card carries its evidence, the move, a spec and a success criterion. Filter by title, site, tag or kind.

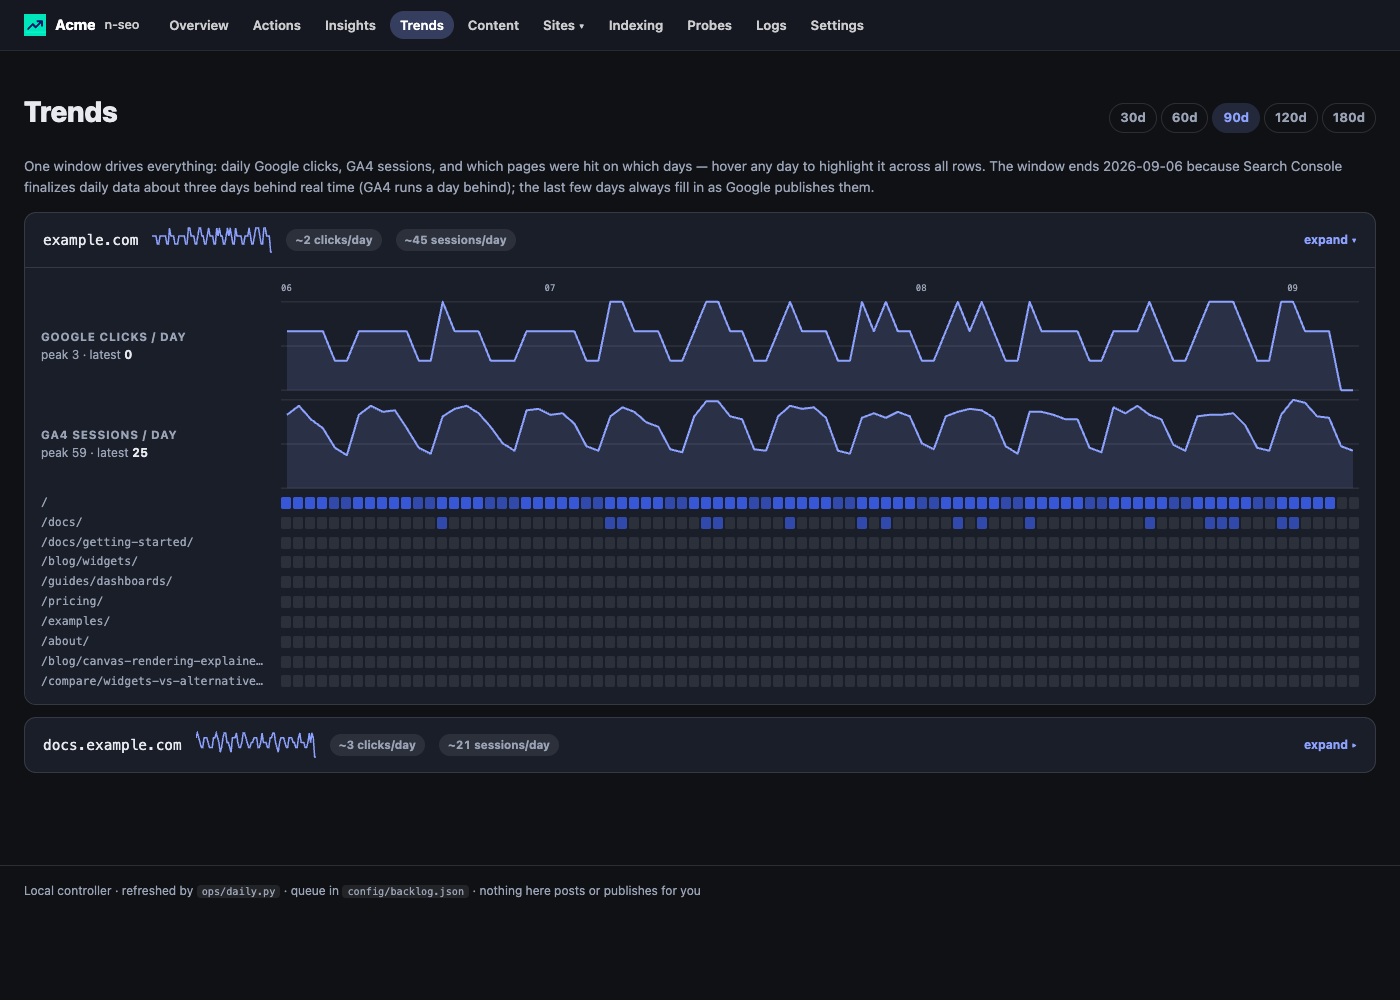
One window drives everything: clicks per day, sessions per day, and which pages were hit on which days. Hover a day to highlight it across every row.

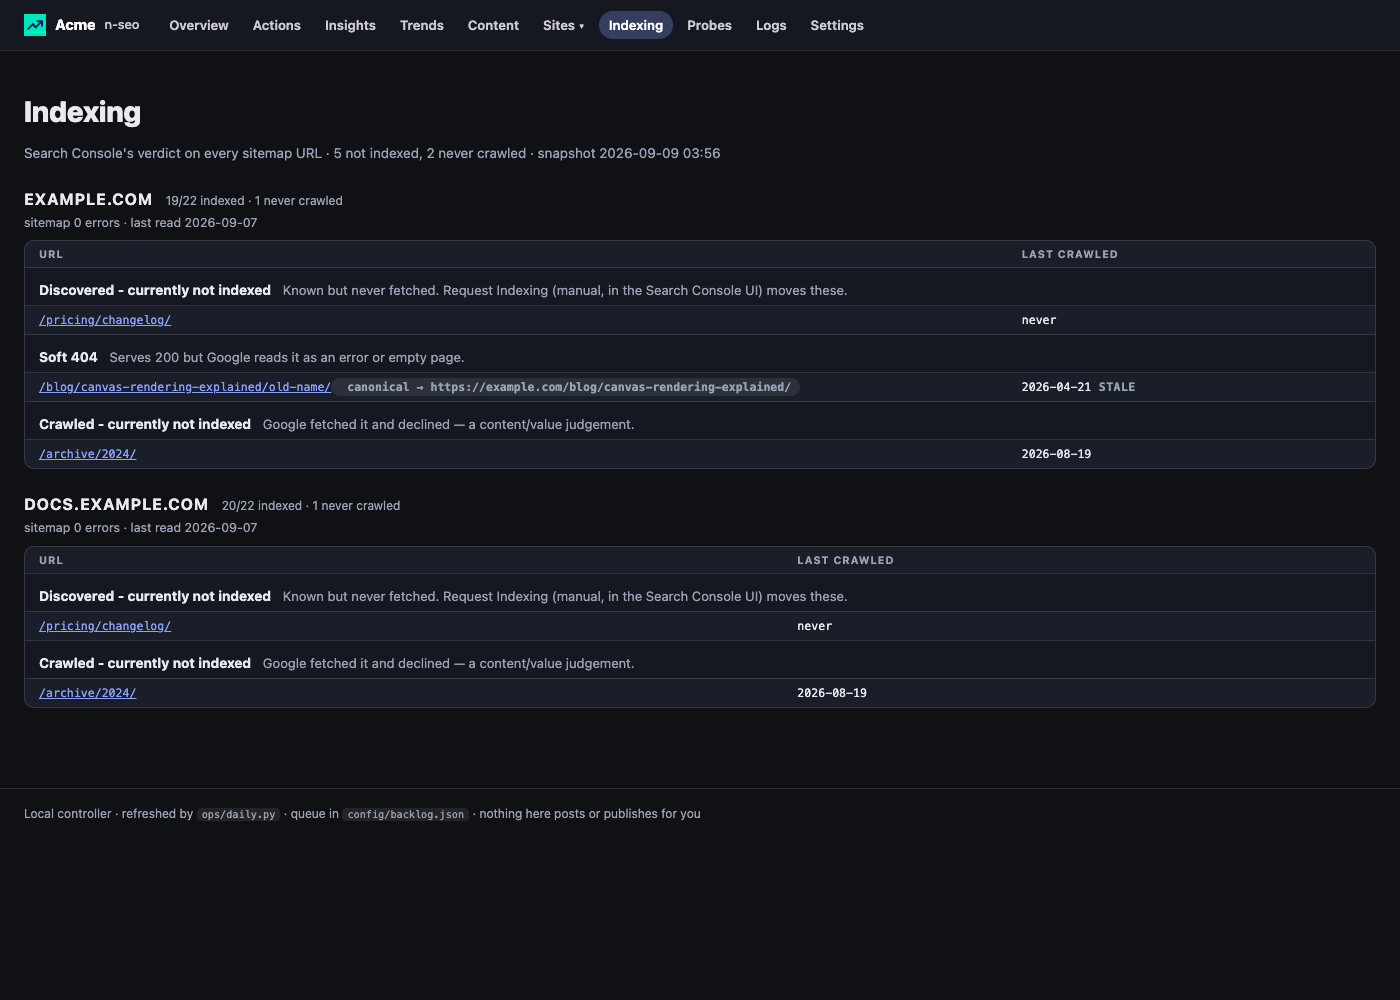
Search Console's verdict on every URL in your sitemap. Tells "nobody searches for this" apart from "Google has never fetched this" — they look identical in performance data.

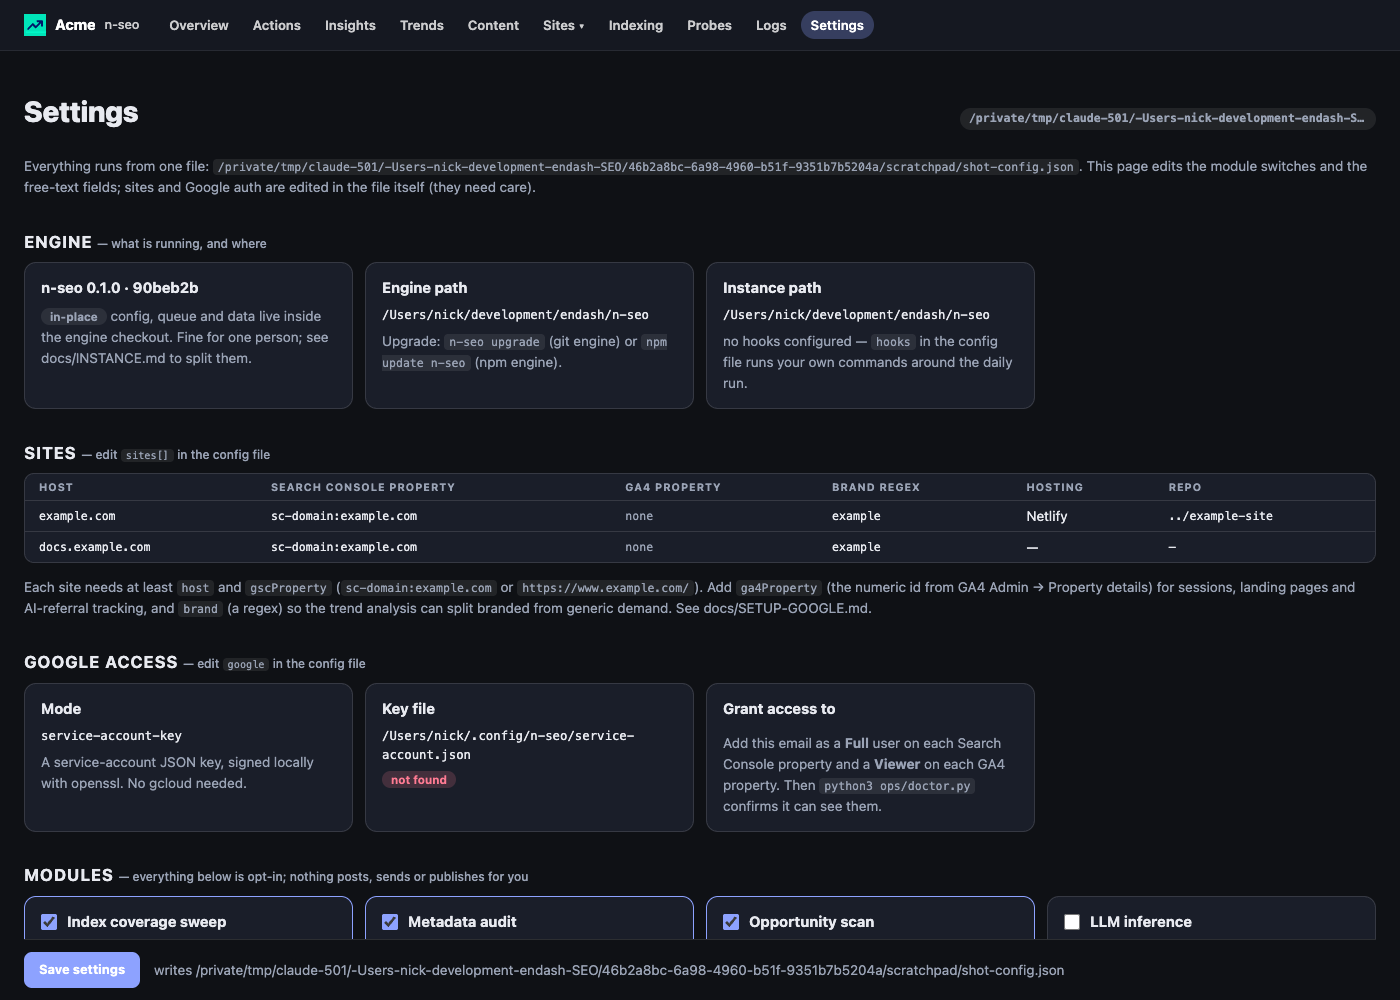
One config file, edited from the page. Toggle modules, set the digest topics, describe your expertise for briefings, list the pages to watch.
Also: per-site pages (striking distance, CTR gaps, landing pages, AI-referral sources), Insights, Probes, Logs, Content (drafts, campaigns, participation briefings).
n-seo ships with an opinionated operating model. Each rule is a few lines you can read, argue with and change. The queue shows you why it thinks so, every time.
After you rewrite a page's title or description, leave it alone for four weeks. Churn reads as manipulation and resets Google's evaluation. Measure, then move.
Twenty-five title rewrites in one afternoon is a pattern. Stagger the batches across your sites.
Decisions ride the trailing 90 days so a fix you shipped last week stops being accused. The long window is for totals and history.
The clicks-per-month number on a card exists to rank the queue. It is not a promise, and the tool never reports it as one.
Done work stays on the board with a dated note until the data has spoken. Deleting it is how you forget what you learned.
Community participation is human. The tool finds the thread and briefs you on the gist, the debate and your genuine angle. It will not write the words.
n-seo ships with our operating model because a tool with no opinion is a spreadsheet. Yours is probably different, and better for your clients. Every part of the model is a file you can change — and the engine was built from the start to run more than one portfolio.
The code lives in one place; each client's config, queue, drafts and data live in a directory of their own, with their own git history. Upgrading the engine touches none of it. Run ten instances off one install.
The operating rules are documentation, the queue is a JSON file you curate, and the agent skills that enforce your process are markdown. Disagree with the 28-day freeze? Change it. Fork the engine if you want to go further — the instance split means you can still pull upstream.
The static export publishes a read-only mirror behind your own sign-in, refreshed by the morning run. Clients see the queue, the evidence and what shipped, whenever they look — and stop asking you for status.
Everything beyond the core pulls is off until you turn it on. Nothing here posts, sends or publishes on your behalf.
| Module | What it does | Needs | Default |
|---|---|---|---|
| Index coverage sweep | URL Inspection verdict for every sitemap URL | Search Console access | on |
| Metadata audit | Fetches each ranking page's live title and description, judges them against the queries it ranks for | — | on |
| Opportunity scan | 84-day trend refresh; rising queries no queue item covers become candidates | — | on |
| LLM inference | Turns candidates into proposals and watched items into verdicts; writes digest briefings | a provider you choose: any stdin CLI, or an Anthropic / OpenAI-compatible endpoint | off |
| Hacker News digest | Finds fresh threads in your expertise areas and briefs you on each | your HN username | off |
| Reddit digest | Same for subreddits | a free Reddit "script" app's credentials | off |
| IndexNow | Key generation and pings to Bing / Copilot / Yandex on publish | — | off |
| Static export | Snapshot the dashboard to HTML for a mirror behind your own auth | — | off |
| Git auto-commit | Commit the daily log after each run | a git remote, optionally | off |
| Notifications | Desktop notification when a step fails | macOS | off |
Run the demo, connect a site, read the queue tomorrow morning.